





Karsten Wenzlaff, Advisor
August 26th, 2025
Karsten Wenzlaff is a Crowdfunding and Fintech Expert from Germany. He is Secretary-General of Digit[...]


Aug 17, 2026

A mid-size alternative lender in Vilnius pulls company registry filings, marketplace pricing and sanctions lists into its underwriting model every night. None of it is illegal to read. Most of it becomes a liability the moment it is copied, stored and combined with something else. That gap between "publicly visible" and "lawfully processed" is where fintech compliance teams keep losing arguments with their own data science departments.
Public web data – company filings, marketplace listings, court dockets, sanctions databases, social media bios – has become a standard input for credit scoring, fraud detection, KYB and competitive pricing in financial services. In Meta Platforms v. Bright Data, a federal district court held that Bright Data had not breached Meta's terms of service by collecting data from logged-out pages, which was the specific conduct at issue. The ruling turned on Bright Data's particular conduct and its contractual relationship with Meta rather than establishing a general rule for scraping public websites. For a regulated entity, that distinction is not academic. A bank's third-party risk team, an EU DORA auditor or a state attorney general does not care whether the data was "technically public" if the collection method itself created exposure.
hiQ Labs v. LinkedIn is still the reference case for US practitioners, and it is more nuanced than the headlines from 2019 suggest. The Ninth Circuit held twice, first in 2019 and again on remand in 2022, that scraping data from pages open to any visitor does not amount to accessing a computer "without authorization" under the Computer Fraud and Abuse Act. That took the CFAA off the table as a criminal exposure for reading public pages. It did not end the case. hiQ and LinkedIn settled the remaining contract claims in 2022, and hiQ agreed to destroy the data it had already collected and pay damages, because its scraping still violated LinkedIn's user agreement. The lesson for a fintech legal team is specific: CFAA risk and contract risk are two separate questions, and winning on one does not close the other.
On the EU side, the CFAA question barely matters, because GDPR does not distinguish between public and private personal data. Article 4 defines personal data by whether it relates to an identifiable natural person, not by where it was found. A LinkedIn bio, a court filing with a defendant's name, or a marketplace seller profile with a real name attached all fall inside GDPR's scope the moment they are collected, and Article 6 still requires a lawful basis – legitimate interest is workable for adverse-media or fraud screening, but it requires a documented balancing test, not just a note in a Confluence page.
Four use cases account for most of the public-data traffic coming out of fintech data engineering teams. Alternative underwriting pulls e-commerce store metrics, invoice marketplaces and gig-platform ratings to score borrowers who lack conventional credit files – Kabbage and, later, Amex built entire product lines on this. AML and sanctions screening cross-references OFAC, EU and UN lists against onboarding data, refreshed daily because list updates are unscheduled. Competitive pricing intelligence in embedded finance and BNPL tracks merchant-facing rates across marketplaces to benchmark interchange and fee structures. Fraud and adverse-media screening checks court records, press mentions and social profiles as a secondary signal alongside device fingerprinting.
Not all four carry the same regulatory weight. The table below is the one compliance teams actually need before greenlighting a collection project, not a generic "data source" taxonomy.
| Data source | Typical fintech use | Regulatory sensitivity | Main legal basis to check |
| Company registries (Companies House, EDGAR, EU BRIS) | KYB, beneficial ownership checks | Low to medium | Public register rules and applicable data protection law; filings may contain personal data of directors, officers, beneficial owners and other natural persons |
| Sanctions and PEP lists (OFAC, EU, UN) | AML/KYC screening | Low | Government-published, but update frequency and source authenticity matter |
| E-commerce and marketplace pricing | Competitive intelligence, embedded-finance pricing models | Low to medium | Terms of service and contract law; CFAA exposure may be lower for pages accessible without login (per hiQ v. LinkedIn) |
| Public social media profiles | Alternative credit signals, fraud indicators | Medium to high | GDPR/CCPA personal-data rules apply even if the profile is public |
| Court records and litigation databases | Adverse media, fraud investigation | High | Jurisdiction-specific rules on re-use of judicial data (varies widely, e.g. France's Article 33) |
The engineering choices matter as much as the legal analysis, because a regulator or a bank's third-party risk assessor will ask for logs, not intentions. A defensible pipeline has five properties, and they map to concrete infrastructure decisions rather than policy statements.

Figure 1
Figure 1. Each control maps to an artifact a third-party risk assessor can actually inspect. The first four are described below; request logging is the fifth, and the one the practical takeaway returns to.
Reading a site's robots.txt crawl-delay directive and setting concurrency accordingly is a five-minute engineering task that changes the legal character of the whole program. A crawler hitting a company registry at 200 requests per second looks like a denial-of-service test to the target's security team, regardless of what the data is used for afterward. Most production fintech scrapers we've reviewed cap at 1 request per 2-4 seconds per domain, which keeps CPU load on the target negligible and avoids the WAF triggers that generate abuse complaints in the first place.
This is the point where proxy infrastructure choice stops being a procurement decision and starts being a compliance decision. Rotating through residential or datacenter IPs to maintain a stable success rate against rate limits is standard engineering practice. Rotating IPs specifically to re-access a source after being blocked for a terms-of-service violation is the fact pattern that turned hiQ's win on CFAA into a loss on contract claims. The distinction sounds semantic until an opposing counsel reconstructs your request logs during discovery.
Filtering personal identifiers (names, emails, phone numbers, biometric-adjacent fields) before the data lands in a warehouse is materially cheaper than filtering it after ten analysts have already queried the raw table. A regex-and-NER pass at the collection layer, logged with a timestamp and a rule version, is the artifact a DPO can actually show an auditor.
GDPR's storage limitation principle (Article 5(1)(e)) and most US state privacy laws expect a defined retention period. "We keep everything indefinitely for model retraining" is the single most common finding in the DPIAs we've read for alt-data underwriting programs, and it is usually fixable with a 90-180 day rolling window plus a documented exception process for flagged accounts.
Proxy and scraping infrastructure choice affects three things a compliance file will ask about: whether the vendor itself runs KYC on IP sourcing, whether the billing model matches your actual usage pattern (per-IP monthly vs. per-GB bandwidth), and whether the vendor's own terms indicate the network is ethically sourced rather than built from compromised devices.
| Provider | Billing model | Entry price | Where it fits a fintech workload |
| Proxys.io | Per dedicated IP / month | From $1.40/mo (individual IPv4), $0.13/mo (IPv6) | Steady, low-volume monitoring jobs (registry checks, sanctions list refresh) where a fixed, auditable IP per data feed is easier to log than rotating bandwidth pools |
| Decodo (formerly Smartproxy) | Per GB, tiered | $2.00-$3.75/GB depending on volume | Mid-volume scraping across many source domains where bandwidth, not IP count, is the cost driver |
| Oxylabs | Per GB, sales-assisted | Roughly $8/GB at entry tier, KYC required before provisioning | Enterprises that want a vendor-side KYC record as part of their own third-party risk file |
| Bright Data | Per GB (PAYG or committed) | $8.40/GB PAYG residential, down to ~$3/GB committed; datacenter from ~$0.90/GB | Large, multi-region collection programs where volume discounts offset the higher entry rate |
The billing model split matters more than the headline price. A sanctions-list refresh job that hits the same twelve government sources every night at a predictable, low volume is a poor fit for per-GB bandwidth pricing – you're paying for a metric (data transferred) that has almost nothing to do with your actual constraint, which is IP reputation and consistency of access over time. Vendors like Proxys.io bill per dedicated IP per month, which lines up better with that access pattern and makes cost forecasting for a fixed set of monitored sources straightforward. A marketplace-pricing crawl that touches thousands of product pages across dozens of domains is the opposite case: bandwidth is the real cost driver, and a per-GB model from Decodo, Oxylabs or Bright Data scales more predictably with that workload. Enterprises already running Oxylabs' or Bright Data's own KYC process may lean on that as one input to their own vendor risk assessment, though it doesn't substitute for one.
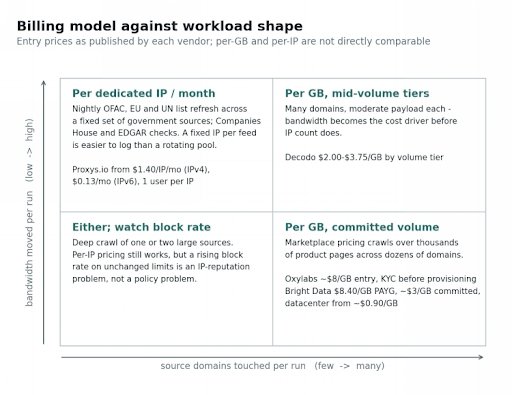
Figure 2
Figure 2. The two variables that move cost are how many domains a run touches and how much data it moves, not the headline price per unit. Per-IP and per-GB rates are quoted in different units and cannot be compared directly.
None of these vendors, including the ones with published ethics or KYC pages, remove the fintech's own obligation to define a lawful basis, log what was collected, and honor retention limits. The proxy layer solves an availability and reliability problem – consistent access to public pages without disproportionate load on the source – not a data protection problem.
Three signals usually mean a proxy or scraping setup needs to change, independent of price. First, a rising block rate on sources with unchanged rate limits – that's an IP-reputation problem the vendor's pool has accumulated, not something a compliance policy fixes. Second, the compliance team asking for source-level access logs the engineering stack can't currently produce – that's a signal the collection layer needs structured logging before it needs a new vendor. Third, a shift in workload shape, for example moving from a handful of steady, low-volume registry checks to broad multi-domain marketplace crawling, which usually means the per-IP pricing that worked for the first case stops making sense for the second.
A fintech data program built on public web sources holds up under regulatory review when three things are documented before the first request is ever sent: the lawful basis for each data category (not a blanket justification), the technical controls that keep collection proportionate to the source (rate limits, minimization, retention), and a request log detailed enough to reconstruct what was collected and why if a regulator or a counterparty's third-party risk team asks. The infrastructure vendor is a smaller decision than most procurement processes treat it as – it changes reliability and cost, not the underlying legal analysis.
 The National Crowdfunding & Fintech Association (NCFA Canada) is a financial innovation ecosystem that provides education, market intelligence, industry stewardship, networking and funding opportunities and services to thousands of community members and works closely with industry, government, partners and affiliates to create a vibrant and innovative fintech and funding industry in Canada. Decentralized and distributed, NCFA is engaged with global stakeholders and helps incubate projects and investment in fintech, alternative finance, crowdfunding, peer-to-peer finance, payments, digital assets and tokens, artificial intelligence, blockchain, cryptocurrency, regtech, and insurtech sectors. Join Canada's Fintech & Funding Community today FREE! Or become a contributing member and get perks. For more information, please visit: www.ncfacanada.org
 |  |  |
|---|---|---|
 |  |  |



August 26th, 2025

January 4th, 2024

June 1st, 2021

September 9th, 2020

July 9th, 2018

January 3rd, 2018

September 25th, 2017

June 20th, 2017

May 10th, 2017

December 14th, 2016

Leave a Reply